A Repeatable Keyword Research Workflow
Turn a broad market into a prioritized keyword plan without drowning in spreadsheets. This guide gives you a measurable workflow, practical benchmarks, and a 30-day action plan.
5 minute read
Most teams do not struggle with a repeatable keyword research workflow because they lack ideas. They struggle because the work is disconnected from a commercial decision, a measurable baseline, and a repeatable operating rhythm. The useful question is not whether a tactic is fashionable; it is whether it improves the quality, speed, or economics of customer acquisition.
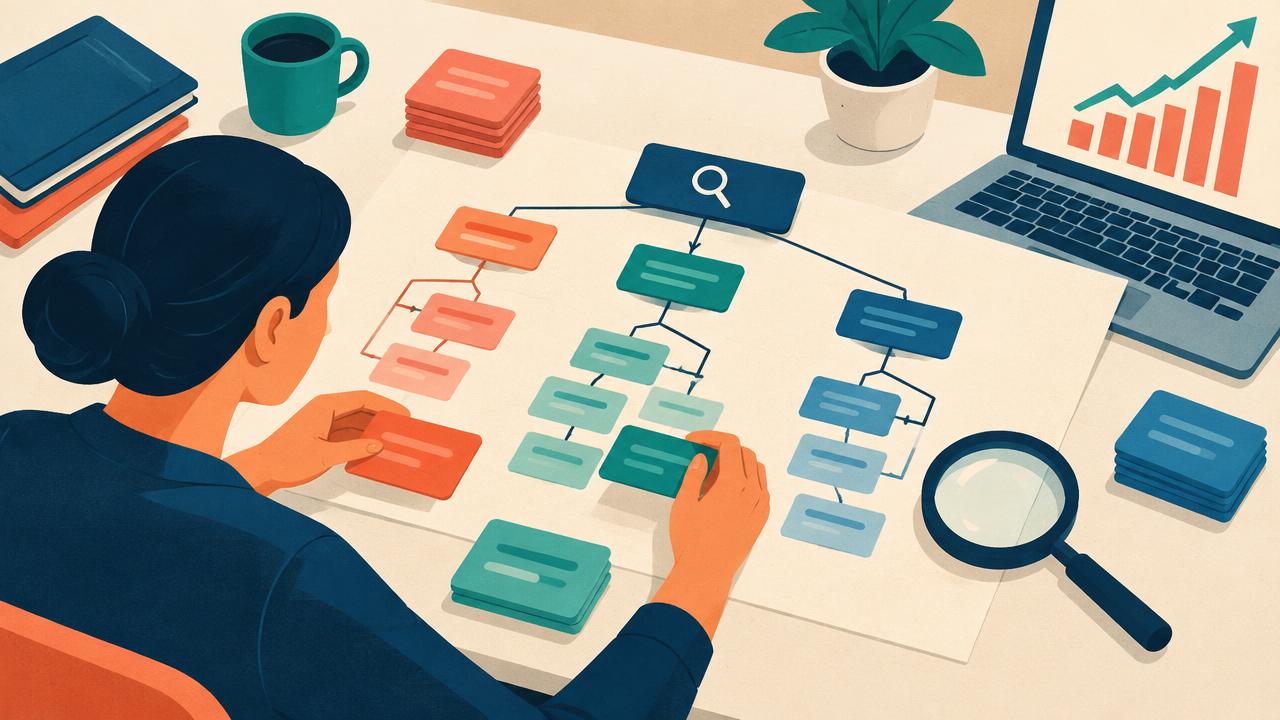
This guide turns a repeatable keyword research workflow into a practical system. It focuses on intent-led clusters, SERP overlap, and business potential, with checkpoints a small team can run using ordinary analytics and a disciplined weekly review. The numbers are starting ranges, not universal laws: use them to form a test, then replace them with evidence from your own audience.
Start with the decision, not the channel
Write one decision at the top of the brief: what should change if this work succeeds? For seo & organic traffic, that may be a qualified visit, a lower acquisition cost, a higher activation rate, or more revenue from an existing audience. Choose one primary outcome and two guardrails. A practical baseline uses the previous 28 days, compared with the prior 28 days, while noting launches or seasonal events that distort the comparison.
Next, define the unit of analysis. Measure intent-led clusters at the level where someone can act: page template, campaign, audience, message, or cohort. Account-wide averages hide the exact place where performance changes. Record volume, rate, and value together. A 20% conversion lift on 40 visits is a clue; a 4% lift on 40,000 visits may be a business result.
Set a minimum evidence threshold before reviewing results. For directional tests, wait for at least two normal business cycles and enough conversions to avoid reacting to one unusually good day. When volume is low, prefer larger qualitative differences and customer interviews over false statistical precision. The aim is a better decision, not a prettier report.
Build the intent-led clusters workflow
“The goal is not to collect more seo & organic traffic activity. It is to make the next commercial decision with less uncertainty.”
Begin with an inventory. List the active assets, owners, audiences, and intended outcomes connected to intent-led clusters. Mark each item as keep, improve, consolidate, or stop. Teams often discover that 20–30% of their workload exists only because nobody has explicitly retired it. Removing weak work creates capacity before a new budget is requested.
Create a simple scoring model from one to five for potential impact, confidence, and effort. Multiply impact by confidence, then divide by effort. The score does not make the decision for you; it exposes disagreements early. Add a strategic-fit flag so a small experiment that teaches an important lesson can outrank an easy but inconsequential optimization.
Assign one owner and one review date. Shared ownership usually means delayed ownership. The owner should document the starting state, implement the smallest meaningful change, and capture what happened. Keep a decision log with the hypothesis, change, result, and next action. After a quarter, this log becomes more valuable than a folder of dashboards because it preserves why choices were made.
Measure SERP overlap without fooling yourself
Measurement for SERP overlap should connect exposure, response, and business value. Start with a primary metric close to revenue, then add a diagnostic metric that explains movement. For example, pair conversion rate with qualified conversions, or click-through rate with revenue per visitor. A rate can improve simply because low-quality volume disappeared, so always retain the denominator.
Use consistent naming. Campaign names, content tags, and source parameters should follow a written convention that a new teammate can understand. Reserve a weekly 15-minute data-quality check for broken events, sudden zeroes, duplicated conversions, and unexplained source changes. One missing tag can invalidate a month of channel comparison.
Treat platform-reported attribution as a claim, not a ledger. Reconcile it against analytics and customer records at least monthly. Differences are expected because windows and identity rules vary. Large directional gaps deserve investigation; small gaps should not consume the entire review. Where stakes are high, use geographic or audience holdouts to estimate incrementality.
| Review area | Healthy signal | Warning signal | Action |
|---|---|---|---|
| Intent-Led Clusters | Clear owner and baseline | Activity without outcome | Rewrite the brief |
| Serp Overlap | Stable definitions | Conflicting reports | Audit tracking |
| Business Potential | Controlled iteration | Many variables change | Narrow the test |
| Economics | Marginal return holds | Blended average hides decline | Slow the scale-up |
Improve business potential through controlled experiments
For business potential, change one meaningful variable per test round. This does not mean every visual detail must remain frozen; it means the hypothesis should be interpretable. Name the expected mechanism: clearer relevance, stronger proof, less friction, or better qualification. If the result changes, the team should know what principle to reuse.
Plan a portfolio rather than one heroic test. A sensible monthly mix is roughly 60% improvements to proven work, 25% adjacent experiments, and 15% high-uncertainty ideas. The exact split can change with runway and maturity, but reserving capacity prevents urgent optimization from eliminating long-term learning.
Scale in steps. Increase reach or budget by 15–25%, then observe a full response cycle before the next increase. Watch marginal performance, not only blended performance. The first segment of an audience is often cheaper and more responsive than the next; assuming constant returns is one of the fastest ways to turn a winner into an expensive average.
A 30-day operating plan
In week one, capture the baseline, audit tracking, and interview two people closest to customers. In week two, rank opportunities and ship the smallest high-confidence change. In week three, review early diagnostics without declaring victory. In week four, decide to scale, iterate, or stop, and write the reason in the decision log.
Keep the weekly review short. Ask four questions: What changed? Why do we think it changed? What will we do next? What could prove us wrong? If a dashboard cannot help answer one of those questions, remove it from the meeting. Clarity creates speed, while extra metrics often create negotiation.
The strongest teams also define a stop rule. Stop when the economics remain below the acceptable threshold after two material iterations, when the required volume is unavailable, or when the opportunity cost exceeds the likely upside. Stopping is not failure; it is how a focused program funds the next useful test.
Conclusion
A Repeatable Keyword Research Workflow works when the team connects craft to a decision, protects measurement quality, and improves one system over time. Start with the 30-day plan, keep the metrics close to commercial value, and let documented evidence—not channel folklore—determine the next investment.